


Updated Sep-2026 Category-Manager Free Exam Files Downloaded Instantly
Practice Exams and Training Solutions for Certifications
NEW QUESTION # 23
Who benefits from a successful promotion?
- A. Manufacturer
- B. Shopper
- C. All of the above
- D. Retailer
Answer: C
Explanation:
The correct answer is D .
A successful promotion should create value for all three parties: the retailer , the manufacturer , and the shopper . The CPCM material explains that promotion is "a key driver of incremental sales" and "an important point of differentiation for retailers." It also states that promotion is reviewed from both a marketing perspective and a promotion/flyer program perspective, including planning, execution, assessment, incrementality, price, ad space, display support, seasonality, competition, ROI, and breakeven.
The retailer benefits through incremental sales, traffic, basket growth, differentiation, and category performance. The manufacturer benefits through increased product movement, brand visibility, trial, and potential share gain. The shopper benefits through value, awareness, savings, and purchase motivation.
Option A is incomplete because the retailer is not the only beneficiary. Option B is incomplete because manufacturers benefit only when the promotion also works in the retail context. Option C is incomplete because shopper value is necessary but not sufficient. A promotion is truly successful when it produces a win for the shopper, retailer, and manufacturer.
NEW QUESTION # 24
The simplest form of regression analysis is _____, where the relationship between variables is modeled as a straight line.
- A. Linear Regression
- B. Decision Tree Regression
- C. Polynomial Regression
- D. Quantile Regression
Answer: A
Explanation:
The correct answer is A .
Linear regression is the simplest regression form because it models the relationship between variables using a straight line. In pricing analytics, this can be used to estimate how sales, demand, or profit changes as price changes, assuming the relationship can reasonably be represented in linear form. The CPCM pricing analytics material includes correlation and price regression analysis as tools for evaluating historical pricing and projecting future sales and profit at specific price points.
Option B, quantile regression, estimates conditional quantiles rather than the average relationship, so it is more specialized. Option C, polynomial regression, models curved relationships using polynomial terms, so it is not the simplest straight-line model. Option D, decision tree regression, uses branching rules rather than a straight-line equation. The phrase "modeled as a straight line" makes Linear Regression the only correct answer.
NEW QUESTION # 25
What is the primary purpose of Consumer Decision Trees (CDTs) in shelf organization?
- A. To predict how changes in assortment will affect sales.
- B. To determine the most popular products in a category.
- C. To map the mental path shoppers take as they shop a category.
- D. To reflect actual buying patterns and substitutions.
Answer: C
Explanation:
The correct answer is A .
Consumer Decision Trees are used to organize the shelf around how shoppers think and shop the category.
CMKG's space-management guidance states: "Use the consumer decision tree for the best layout based on how the Shopper shops the section." That is the cleanest supporting extract for this question. The CDT is not simply a sales-ranking tool; it reflects the shopper's decision hierarchy, such as category, segment, need state, brand, size, flavor, form, or price tier, depending on the category.
Option B is wrong because identifying popular products is a sales-ranking exercise, not the purpose of a CDT.
Option C is closer to assortment simulation or predictive modeling. Option D has some relevance because buying patterns and substitution can inform a CDT, but the best definition is broader: CDTs map the shopper' s decision path through the category.
NEW QUESTION # 26
What does Shrink % measure in inventory management?
- A. The percentage of profit generated from promotional activities.
- B. The percentage of inventory replenished to maintain stock levels.
- C. The percentage of inventory sold during a specific time period.
- D. The percentage of inventory lost due to theft, spoilage, damage, or administrative error.
Answer: D
Explanation:
The correct answer is B .
Shrink percentage measures inventory loss. The CPCM Retailer Economics course teaches how retail math ties into retailer financial results and why suppliers and retailers need to understand the drivers of the financial statement. Shrink is one of those retail financial drivers because inventory that is lost, damaged, spoiled, stolen, or misrecorded reduces available stock and hurts profitability.
The National Retail Federation defines shrink as inventory loss measured as a percentage during a specific inventory period and states that shrink calculations include theft, administrative or operational errors, mistakes, and other identified inventory loss.
Option A describes sell-through or inventory movement, not shrink. Option C describes promotional profitability, not inventory loss. Option D describes replenishment rate or stock maintenance, not shrink.
Shrink is a loss-control and profitability metric, not a sales or replenishment metric.
NEW QUESTION # 27
Which action would BEST reduce shrink in a perishable category?
- A. Order large quantities for better pricing
- B. Increase promotion frequency
- C. Improve forecasting and shelf-life rotation
- D. Add more branded items to the assortment
Answer: C
Explanation:
The correct answer is D .
Perishable shrink is mainly controlled by matching supply to expected demand and rotating product before it expires. CMKG's Retailer Economics and Product Supply Chain material emphasizes that category managers need to understand how their decisions affect the retailer income statement and cost of goods sold, while category management and supply chain must be better aligned for store-level execution.
Improved forecasting reduces over-ordering and excess inventory. Shelf-life rotation ensures older or earlier- expiring product is sold first. FIFO/FEFO rotation is a standard perishable inventory control method because it helps reduce waste and spoilage by moving product before expiration.
Option A may help clear inventory in some cases, but increasing promotion frequency is not the best root- cause control for shrink. Option B is dangerous in perishables because larger orders can increase spoilage if demand is overestimated. Option C changes assortment composition but does not directly control spoilage, dating, or inventory loss. The strongest operational answer is improve forecasting and shelf-life rotation .
NEW QUESTION # 28
What is the best data source to understand how a Retailer is performing in a Category versus their competitors in the market?
- A. Retailer Loyalty Data
- B. Retailer POS Data
- C. Syndicated POS Data
- D. Syndicated Panel Data
Answer: C
Explanation:
The correct answer is D .
The CPCM course identifies Building Data Competency: POS Data as part of the CPCM curriculum and explains that POS data includes retailer and third-party scanned sales data, with trends, sales, profitability, distribution, and shopper insights reviewed in the context of retail POS data.
The phrase "versus their competitors in the market" is the key. A retailer's own POS data shows that retailer's internal sales, but it does not show how competing retailers are performing. Syndicated POS Data aggregates scanned sales across the broader market, so it is the correct source for comparing retailer category performance against competitors.
Option A is wrong because Retailer POS Data is limited to one retailer's own sales. Option B is wrong because Retailer Loyalty Data explains known shopper behavior within that retailer, not market-level competitor performance. Option C is wrong because Syndicated Panel Data is stronger for household/shopper behavior, not scanned sales comparison across retailers.
NEW QUESTION # 29
Which of the following is the first step in the multivariate clustering process?
- A. Create clusters based on relevancy and opportunity
- B. Calculate product demand potential
- C. Identify store-level demographic profiles
- D. Identify product demographic affinity profiles
Answer: D
Explanation:
The correct answer is A .
The multivariate store clustering process starts by identifying the Product Demographic Affinity Profile , because the analyst first needs to understand which demographic groups have the strongest relationship or affinity with the product/category being studied. ARC's category-specific store clustering guidance identifies
"Identify the Product Demographic Affinity Profile (PDAP)" as a core step and then moves into calculating product demand potential.
This sequence matters. You cannot calculate demand potential correctly until you understand the demographic profile that is most relevant to the product or category. Once the product's demographic affinity is known, the analyst can compare that profile to store-level demographic profiles and then create meaningful clusters based on demand and opportunity.
Option B is later in the process because clusters are created after the relevant product and store-level measures are understood. Option C is important, but it follows the product affinity logic. Option D also comes after identifying the demographic affinity profile.
NEW QUESTION # 30
Which of the following methods is used to collect Shopper Data at the point of sale?
- A. Analyzing online search queries
- B. Shipping products from manufacturers
- C. Scanning items at checkout typically tied to Household Loyalty Cards
- D. Tracking mobile devices in households
Answer: C
NEW QUESTION # 31
The best Predictive Analytic tools use which of the following? Select the best answer.
- A. Statistical Models and Machine Learning
- B. Historical Data, Statistical Models and Machine Learning
- C. Historical Data and Machine Learning
- D. Historical Data and Statistical Models
Answer: B
Explanation:
The correct answer is A .
The CPCM course states that moving into advanced category analytics includes predictive analytics, specifically naming collaborative filtering, clustering algorithms, regression models, and time-to-event models. Those methods require historical data, statistical modeling, and machine-learning-style pattern recognition. IBM defines predictive analytics as predicting future outcomes by using historical data combined with statistical modeling, data mining techniques, and machine learning.
Option A is the most complete answer because predictive analytics needs all three: historical data to learn from, statistical models to quantify relationships, and machine learning to detect patterns and improve prediction. Option B omits machine learning. Option C omits statistical models. Option D omits historical data, which is the base input for predictive analytics.
NEW QUESTION # 32
What are the primary data sources for shopper insights?
- A. Retailer Loyalty
- B. Retailer Loyalty Data, Syndicated Panel Data, Syndicated POS Data and Retailer Loyalty Data
- C. Retailer Loyalty Data and Syndicated Panel Data
- D. Retailer Loyalty Data, Syndicated Panel Data and Syndicated POS Data
Answer: D
Explanation:
The correct answer is B because shopper insights in category management are developed from multiple shopper and sales-data sources, not from loyalty data alone. The CPCM/CMKG material describes the intermediate CPCM program as focused on "in-depth data and analytics across key data sources and category tactics," and its curriculum includes both Panel Data and POS Data as formal data competency areas.
The supporting extract states that standard category management data includes "retail POS, retail measurement data, consumer panel data and 'other' data," and that learners must understand the best data sources for different business issues and key questions.
So the complete set in the answer choices is Retailer Loyalty Data, Syndicated Panel Data, and Syndicated POS Data . Loyalty data helps identify known shopper/household purchasing behavior. Panel data gives a broader consumer/household behavior view. Syndicated POS data provides scanned sales and market-level performance context.
Option A is wrong because it repeats Retailer Loyalty Data and is poorly constructed. Option C is too narrow because it excludes Syndicated POS Data. Option D is incomplete because retailer loyalty data alone cannot provide a full shopper insight picture.
NEW QUESTION # 33
Which factor primarily influences how much room is available for a retail assortment?
- A. Shopper preferences and trends.
- B. Days of supply and case pack requirements.
- C. The number of shoppers that purchase the category.
- D. The number of SKUs in the product mix.
Answer: B
Explanation:
The correct answer is D .
In space planning, the real shelf constraint is not just how many SKUs the team wants. It is whether those SKUs can physically fit while supporting replenishment needs. Days of supply and case pack requirements influence how many facings and how much shelf capacity an item needs. Oracle's assortment and space optimization documentation explains that optimized assortment and placement use available space, product dimensions, expected demand, replenishment schedules, service levels, merchandising rules, and category goals.
This matches the exam logic: a product that needs more days of supply or must hold a full case pack requires more room. That limits how much assortment can realistically fit on the shelf.
Option A is wrong because shopper count affects demand, not the physical room available. Option B influences strategic assortment choices, but it does not directly determine shelf capacity. Option C is an output or planning decision; the number of SKUs must be constrained by space, case pack, and supply requirements.
NEW QUESTION # 34
Which of the following KPIs is most critical for resolving on-shelf availability issues in the retail supply chain?
- A. Gross Margin
- B. Fill Rate
- C. Order Cycle Time
- D. Inventory Turnover
Answer: B
Explanation:
The correct answer is B .
On-shelf availability problems are supply-chain execution problems: the product must be available when the shopper wants to buy it. CMKG explains that supply chain affects inventory, forecasting, availability, cash flow, service levels, and shopper experience. Fill Rate is the most direct KPI among the options because it measures the ability to fulfill demand from available stock without lost sales or backorders. A weak fill rate leads directly to out-of-stocks and poor shelf availability.
Option A, Inventory Turnover, measures how quickly inventory sells through, but high turnover does not guarantee shelf availability. Option C, Gross Margin, is a financial metric, not an availability KPI. Option D, Order Cycle Time, measures replenishment speed, but it does not directly show whether customer or store demand is being fulfilled. Fill Rate is the best answer.
NEW QUESTION # 35
How do planograms support stakeholders across the organization?
- A. They are used by shoppers to find products in stores.
- B. They are used by buying teams to place purchase orders.
- C. They are used to determine shelf placement in stores.
- D. They generate essential data that influences supply chain, shopper experience, and in-store execution.
Answer: D
Explanation:
The correct answer is D .
A planogram is not just a shelf-placement picture. CMKG states that planograms require accurate product dimensions, UPC codes, live images, fixture dimensions, shelf measurements, shopper decision trees, store clusters, shelving standards, and product data such as unit movement, unit price, and unit cost. CMKG also explains that effective planograms connect to the product supply chain, including authorized product distribution lists and shelf-capacity data used by ordering systems.
That makes option D the most complete answer. Planograms support supply chain by providing shelf capacity and replenishment inputs. They support shopper experience by organizing the shelf around how shoppers shop. They support in-store execution by giving stores the layout to implement.
Option A is too narrow because buying teams may use planogram data, but purchase orders are not the main purpose. Option B is true but incomplete. Option C is indirectly true, but shoppers do not "use" planograms in the same way internal stakeholders do.
NEW QUESTION # 36
Which of the following purchase behaviors best explains the category performance?
Dollars: +5%
Number of Households: +2%
Trips per Household: -2%
Units per Trip: +3%
Dollars per Unit: +2%
- A. Increase in Dollars per Unit
- B. Increase in Number of Households
- C. Increase in Total Baskets
- D. Increase in Units per Trip
Answer: D
Explanation:
The correct answer is C .
The category dollars increased by +5% . To identify what best explains that performance, compare the listed purchase-behavior drivers. The strongest positive driver shown is Units per Trip at +3% . Number of Households is also positive at +2%, and Dollars per Unit is positive at +2%, but neither is as strong as Units per Trip. Trips per Household is negative at -2% , so it cannot be the best explanation for growth.
CMKG's shopper analytics explanation supports this type of driver analysis. It explains that sales are driven by household purchasing behavior and spending, and gives the formula: Total Number of Buying Households × Spend per Buying Household = Dollar Sales . CMKG further breaks spending into purchase occasions and spend per trip, which is exactly the kind of logic tested in this question.
Option A is wrong because total baskets are not clearly increasing; the household gain is offset by the decline in trips per household. Option B is partially correct but not the strongest driver. Option D is also positive, but
+2% is lower than the +3% gain in units per trip.
NEW QUESTION # 37
Which of the following methods is used to collect Shopper Data at the point of sale?
- A. Analyzing online search queries
- B. Shipping products from manufacturers
- C. Scanning items at checkout typically tied to Household Loyalty Cards
- D. Tracking mobile devices in households
Answer: C
Explanation:
The correct answer is C because point-of-sale shopper data is generated through checkout scanning activity.
CPCM/CMKG describes POS data as "retail POS data, including retailer and third-party scanned sales data," and explains that the course covers how POS data is derived, key measures, sales, profitability, distribution, and shopper insights.
The phrase "scanning items at checkout" is the key. POS data is created when products are scanned during a retail transaction. When that transaction is tied to a loyalty card, the retailer can connect the basket to a household or shopper profile, which makes it much more useful for shopper analytics.
Option A is wrong because shipping products from manufacturers is supply-chain movement, not shopper data collection. Option B is wrong because online search queries are digital behavior data, not point-of-sale data. Option D is wrong because mobile tracking may show location behavior, but it is not the standard POS collection method tested here.
NEW QUESTION # 38
What is the definition of pricing and its role in the category management process?
- A. Pricing is the monetary value assigned to a product or service, and it directly impacts sales volume, shopper behavior, and category performance.
- B. Pricing is the process of setting promotional discounts to attract more shoppers.
- C. Pricing is the calculation of production costs to determine a product's retail price.
- D. Pricing is the method of categorizing products based on their market value.
Answer: A
Explanation:
The correct answer is B .
Pricing is the monetary value placed on a product or service, but in category management it is more than a simple price tag. It is one of the key category tactics because it affects shopper choice, sales volume, gross margin, profit, and overall category performance. CMKG's pricing guidance states that pricing decisions directly affect category sales, inventory positions, and category profitability, and that price is a major influence on shopper purchase behavior.
Option A is wrong because product categorization is segmentation or assortment work, not pricing. Option C is too narrow because production cost is only one input into price setting; pricing also considers competition, shopper value, elasticity, retailer strategy, category role, margins, and promotional objectives. Option D is wrong because promotional discounting is only one pricing tactic. Pricing includes regular price, promotional price, price thresholds, competitive price positioning, private-label gaps, price elasticity, slope, and margin implications.
NEW QUESTION # 39
What does a high Sales per Point of Weighted Distribution (SPWD) indicate about a product's performance?
- A. It indicates strong sales performance relative to the product's distribution.
- B. It suggests the product is underperforming in its available outlets
- C. It reflects the total revenue generated by the product.
- D. It shows that the product is available in a large number of stores.
Answer: A
Explanation:
The correct answer is D .
SPWD is a velocity/productivity measure. A high SPWD means the product is generating strong sales for each point of weighted distribution it has. In other words, the product is performing well where it is available
, even if it does not yet have broad distribution.
NielsenIQ explains that sales per distribution point accounts for distribution and ranks products on sales productivity based on distribution levels. It also gives the key interpretation: a product with higher total sales is not necessarily more productive if it has much higher distribution. That is exactly why option D is correct.
Option A is the opposite of the correct interpretation. A high SPWD does not suggest underperformance; it suggests strong velocity. Option B is wrong because total revenue alone does not account for distribution.
Option C is wrong because broad availability is measured by distribution or ACV weighted distribution, not by SPWD. A product can have low distribution and still have high SPWD if it sells strongly in the outlets where it is carried.
NEW QUESTION # 40
Define Share of Wallet (SOW) for a retailer.
- A. The proportion of shoppers who enter a store and proceed to make a purchase in a specific category in a single trip.
- B. The proportion of a customer's total spending within a specific product category that goes to a particular retailer, as opposed to competitors, over a given timeframe.
- C. The proportion of shoppers who enter a store and proceed to make a purchase in a specific category over a given timeframe.
- D. The proportion of a customer's total spending within a specific product category that is spent in the marketplace.
Answer: B
Explanation:
The correct answer is B .
Share of Wallet is a retailer shopper-performance measure. It looks at how much of a shopper's total category spending is captured by one retailer versus competing retailers. The CPCM material places this type of analysis inside consumer/shopper analytics, where household panel data is used to understand consumer behavior and the dynamics that drive category and brand performance. The official CPCM course description states that household panel data helps teams "get a clear picture of consumer behavior" and adjust strategies around the consumer dynamics driving category performance.
Option A describes buyer conversion or shopping conversion, not share of wallet. Option C is incomplete because it only says spending in the marketplace; SOW must identify how much of that spend goes to the specific retailer. Option D is also conversion-based because it focuses on shoppers entering a store and buying in a single trip.
NEW QUESTION # 41
Which of the following metrics is used to evaluate space productivity in retail environments?
- A. Customer Foot Traffic
- B. Sales per Square Foot
- C. Inventory Turnover
- D. Net Profit Margin
Answer: B
Explanation:
The correct answer is D .
Sales per Square Foot is the standard retail productivity metric that evaluates how efficiently physical selling space generates revenue. The CPCM program includes Space Management Fundamentals as part of the official CPCM curriculum, and CMKG explains that planograms become more analytical when product performance data such as unit movement, price, and cost are added.
Sales per square foot directly connects sales output to the amount of retail space used. Square explains the calculation as sales divided by the store's sales space and states that it helps evaluate how efficiently sales space is being used.
Option A, customer foot traffic, measures store visits, not space productivity. Option B, inventory turnover, measures how quickly stock sells through. Option C, net profit margin, measures profitability percentage.
Only option D directly evaluates productivity of retail space.
NEW QUESTION # 42
What is the Dollar Sales per $MMACV for the Product Group in Store 478?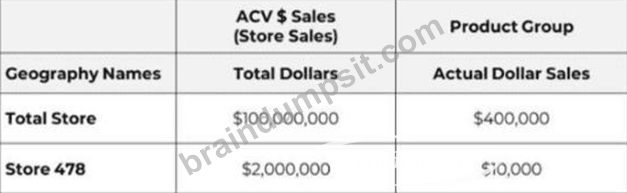
- A. $200
- B. $50
- C. $5,000
- D. $4,000
Answer: C
Explanation:
The correct answer is D .
Dollar Sales per $MMACV measures sales productivity normalized by store or market selling power. CPG Data Insights defines Sales per $MM ACV as a velocity measure calculated by dividing sales by the market's All Commodity Volume expressed in millions, and explains that it helps compare productivity across markets, retailers, or products with different distribution levels.
For Store 478 :
Product Group Actual Dollar Sales = $10,000
Store 478 ACV $ Sales = $2,000,000
ACV expressed in millions = $2,000,000 ÷ $1,000,000 = 2
Calculation:
$10,000 ÷ 2 = $5,000
So the Dollar Sales per $MMACV for the Product Group in Store 478 is $5,000 .
Option C, $4,000, is the total-store benchmark calculation: $400,000 ÷ 100 = $4,000. The question asks specifically for Store 478 , not the total store benchmark.
NEW QUESTION # 43
What is the benefit of tracking SOW for a Retailer in a particular category?
- A. SOW concentrates on the spending habits of all Shoppers who haven't bought from the Retailer with the goal of securing a larger portion of their budget.
- B. SOW concentrates on the spending habits of Shoppers who already buy from the Retailer with the goal of securing a larger portion of their budget.
- C. SOW concentrates on the spending habits of Shoppers who already buy that category in the marketplace with the goal of securing a larger portion of their budget.
- D. SOW concentrates on the spending habits of all Shoppers in the marketplace with the goal of securing a larger portion of their budget.
Answer: B
Explanation:
The correct answer is A .
SOW means Share of Wallet . In category management, it measures how much of a shopper's category spending is captured by a specific retailer, brand, or product compared with the shopper's total category spending. CMKG explains this concept through shopper/consumer panel analysis: "42.8% of their total category dollars were spent on their brand," and identifies that as the brand's "loyalty" number or "share of wallet." That is why option A is correct: SOW focuses on shoppers who already buy from the retailer and helps the retailer understand whether those shoppers are giving more or less of their category budget to that retailer.
The business purpose is to secure a larger portion of those shoppers' spending.
Option B is too broad because it refers to all shoppers who buy the category in the marketplace, not specifically the retailer's shoppers. Option C is wrong because SOW is not mainly about shoppers who have never bought from the retailer. Option D is also too broad because total marketplace shoppers are more relevant to market penetration or market share analysis, not retailer-specific share of wallet.
NEW QUESTION # 44
What is the primary purpose of a promotional strategy?
- A. To manage supply chain operations and inventory levels.
- B. To determine the pricing strategy for all products in the store.
- C. To create a long-term business plan for overall company growth.
- D. To drive product awareness, increase sales, and influence shopper behavior through targeted promotions.
Answer: D
Explanation:
The correct answer is D .
The CPCM course describes promotion as a key driver of incremental sales and a retailer differentiation tool.
It further explains that the promotion course covers promotion from both a marketing perspective and a promotion/flyer program perspective, including planning, execution, assessment, and the factors that affect promotion outcomes.
That directly supports option D. Promotional strategy is used to influence shopper behavior, create awareness, generate incremental demand, support category objectives, and improve sales performance through targeted promotional activity. The promotion must be assessed through lift, incremental sales, subsidy, ROI, breakeven, cannibalization, and other measures because the objective is not merely to run activity; it is to produce measurable business impact.
Option A is wrong because supply chain and inventory are operational support areas, not the primary purpose of promotional strategy. Option B is wrong because pricing strategy is related but separate. Option C is too broad; promotional strategy supports business growth, but it is not the overall corporate business plan.
NEW QUESTION # 45
Which primary data sources are used to answer the 'How' and 'Who' questions in category management?
- A. Focus Groups and In-Store Observations
- B. Retail POS Data and Syndicated POS Market Data
- C. Loyalty Card Data and Household Panel Data
- D. Social Media Analytics and Web Traffic Data
Answer: C
Explanation:
The correct answer is D because Loyalty Card Data and Household Panel Data are the data sources most directly tied to shopper identity, household behavior, trip behavior, repeat purchase, switching, loyalty, and demographics. The CPCM/CMKG material states that household panel data is "one of the primary data sources required to do category management work" and that it provides "a clear picture of consumer behaviour" so strategies can focus on the consumer dynamics driving category and brand performance.
This question is specifically asking about the "How" and "Who" questions. POS data is very strong for answering what sold, where, when, and how much , but it is weaker for answering who the shopper is unless it is connected to household or loyalty information. Loyalty card data identifies known shopper behavior at the retailer level. Household panel data adds broader consumer behavior across trips, baskets, brands, retailers, and demographics.
Option A is wrong because social media and web traffic data may support digital insight, but they are not the core CPCM shopper data sources here. Option B is wrong because POS data is sales-performance data, not the best source for shopper identity. Option C is qualitative research, useful for context, but not the primary data-source pair tested in CPCM shopper analytics.
NEW QUESTION # 46
What does store clustering in category management primarily involve?
- A. Focusing solely on increasing sales volume across all stores.
- B. Grouping retail stores based on specific characteristics or attributes to manage them more efficiently.
- C. Organizing retail stores alphabetically to simplify inventory management.
- D. Assigning identical product assortments to all stores regardless of location.
Answer: B
Explanation:
The correct answer is B .
Store clustering means grouping stores into manageable sets based on shared characteristics, such as shopper demographics, sales history, lifestyle data, competition, store size, store productivity, category demand, and local-market opportunity. CMKG explains that retailers can cluster stores using consumer sales history, demographic and lifestyle data, product attitudes, competition, store size, and store productivity. CMKG also states that clustering creates groups that are differentiated from each other while being homogeneous within the cluster.
Option B is therefore the complete definition. The purpose is to manage stores more efficiently and make better decisions for assortment, merchandising, pricing, promotion, shelving, and shopper marketing.
Option A is wrong because clustering is not only about increasing sales volume; it is about matching decisions to store-level demand and shopper differences. Option C is the opposite of store clustering because clustering exists to avoid treating all stores identically. Option D is administrative sorting, not category management analytics.
NEW QUESTION # 47
......
Q&As with Explanations Verified & Correct Answers: https://examtorrent.braindumpsit.com/Category-Manager-latest-dumps.html